❯ cat projects/personal-atlas.md
Personal Atlas
Personal project · 2026
I parsed 143k Telegram messages (2016–2026) and built visualizations to study my own patterns: how I communicate, how I behave, and how I've evolved across almost ten years.
- my part
- Solo: design, pipeline, analysis.
- stack
- Python, DuckDB, Parquet, sentence-transformers, Ollama, qwen2.5, Hugging Face, scikit-learn
## context
I parsed 143k Telegram messages (2016–2026) and built visualizations to study my own patterns: how I communicate, how I behave, and how I've evolved across almost ten years.
## challenge
Large, messy, deeply private data, and chats that switch between Russian and English. Private messages could never leave my machine.
## what i built
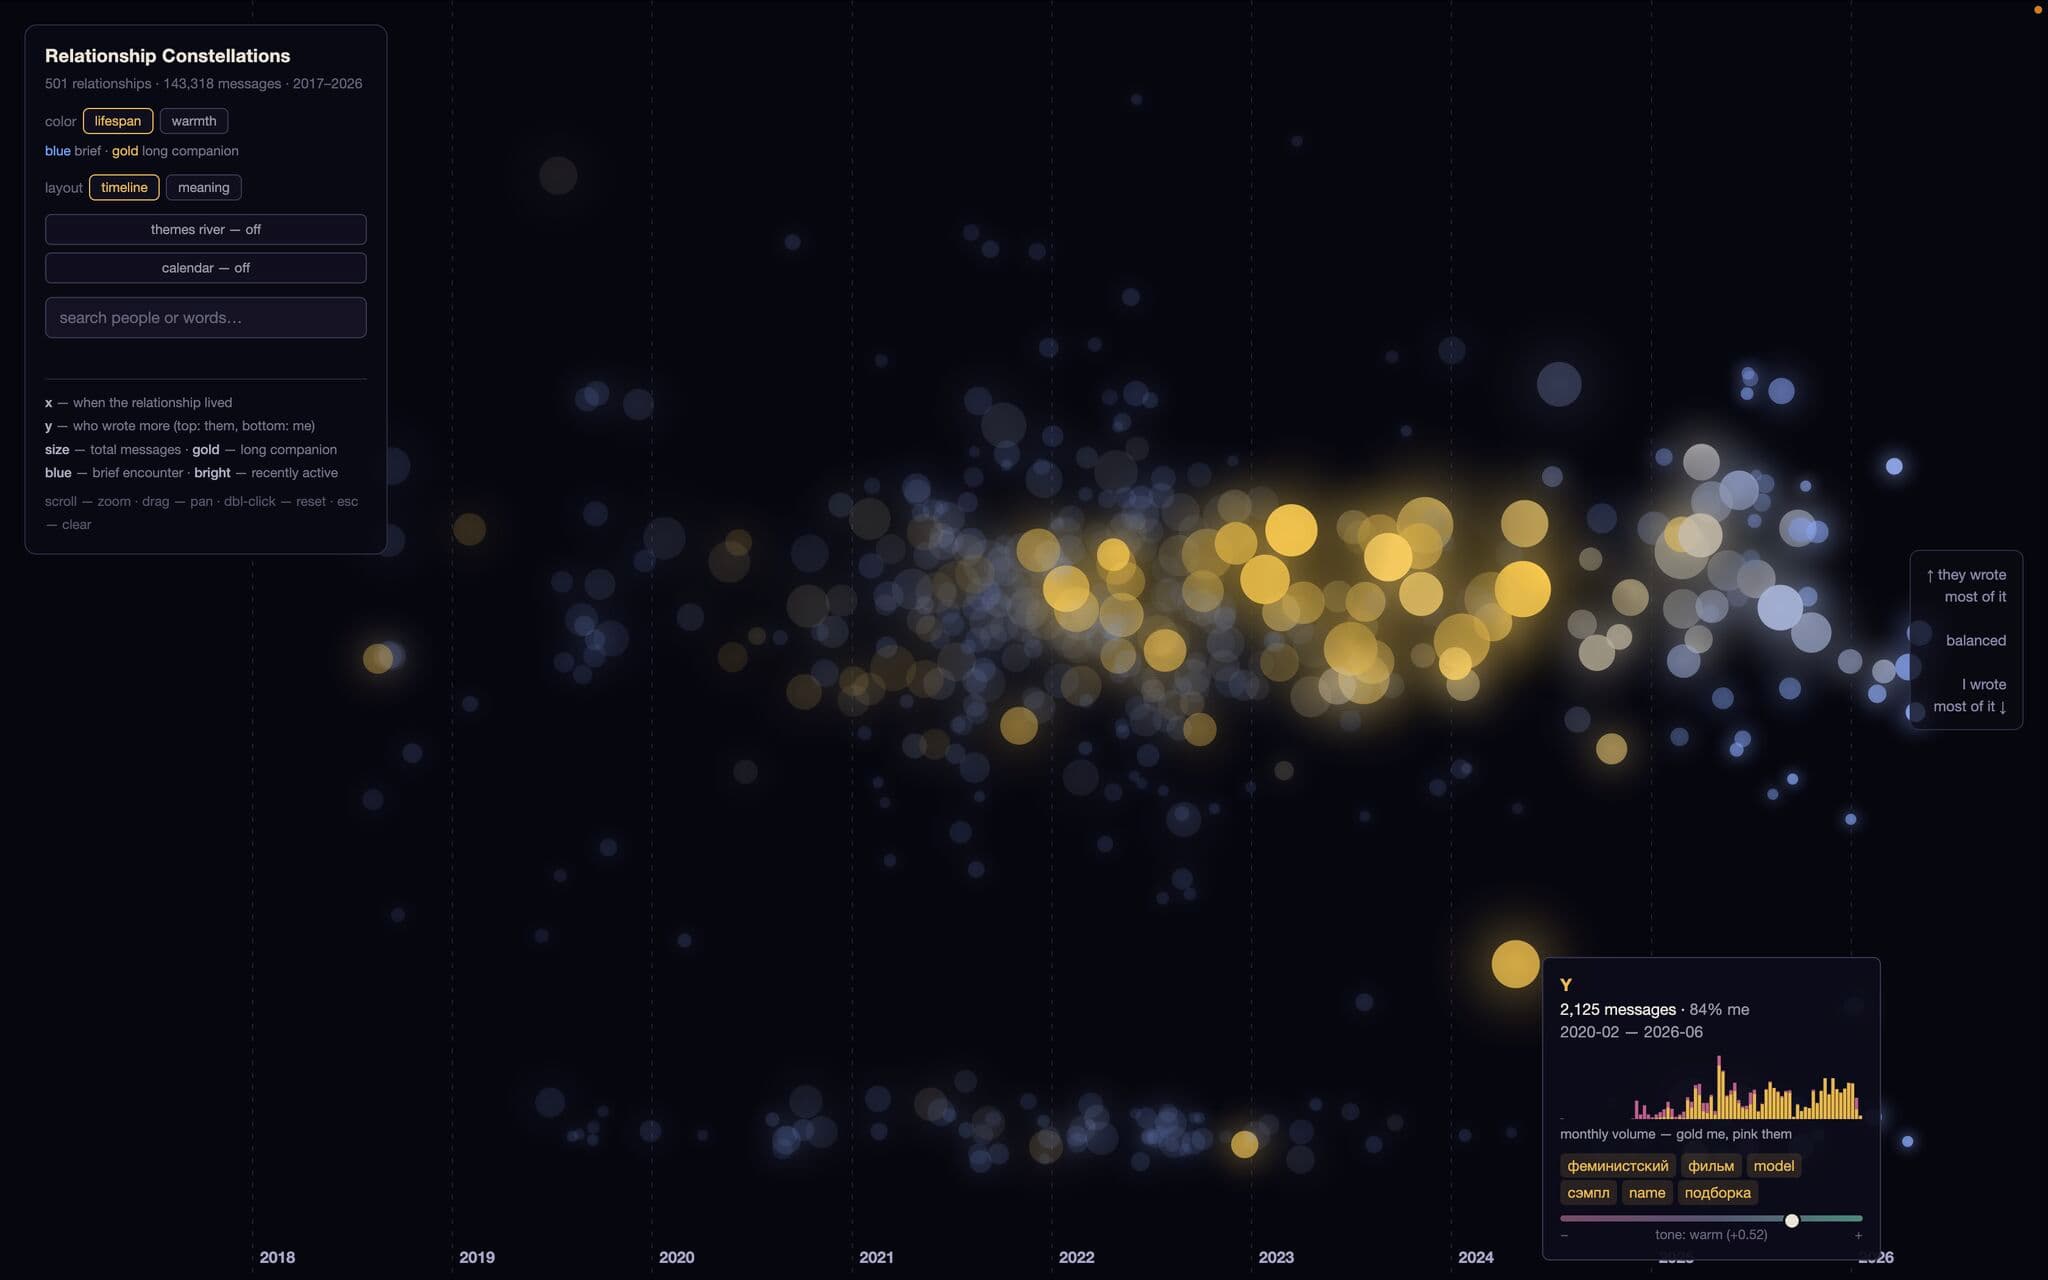
Visualizations of my own patterns: which weeks and hours I was most productive vs. most busy, the words I used most each year, a sentiment heatmap that reads the emotional weather of each relationship month by month (warm stretches vs. tense ones), and the centerpiece: a "constellation" of all 501 chats, every relationship a star, laid out by an embedding model.
## approach & trade-offs
Inspired by Andrej Karpathy's method for building an LLM wiki / knowledge base, the pipeline ingests my own data (mostly Telegram history, plus emails, calendar, location, even medical lab results) into a local vault, then makes it searchable and summarizable. For retrieval, embeddings and semantic search pull the relevant pieces; for generation, a local LLM writes summaries on top. Together, that's RAG. My chats are Russian–English, so I run models that handle both: qwen2.5 via Ollama.
## outcome
Privacy is the main characteristic: private messages never leave my machine.
--
cd .. | next: New Orleans Map